Data Center
Performance.
Edge Efficiency.
Vision, Agentic and Gen AI running on the world's most efficient silicon, from embedded to edge to server.
Manufacturing tumour and brain region segmentation
Gen AI, illustration open models running locally on Axelera silicon
Performance.
Edge Efficiency.
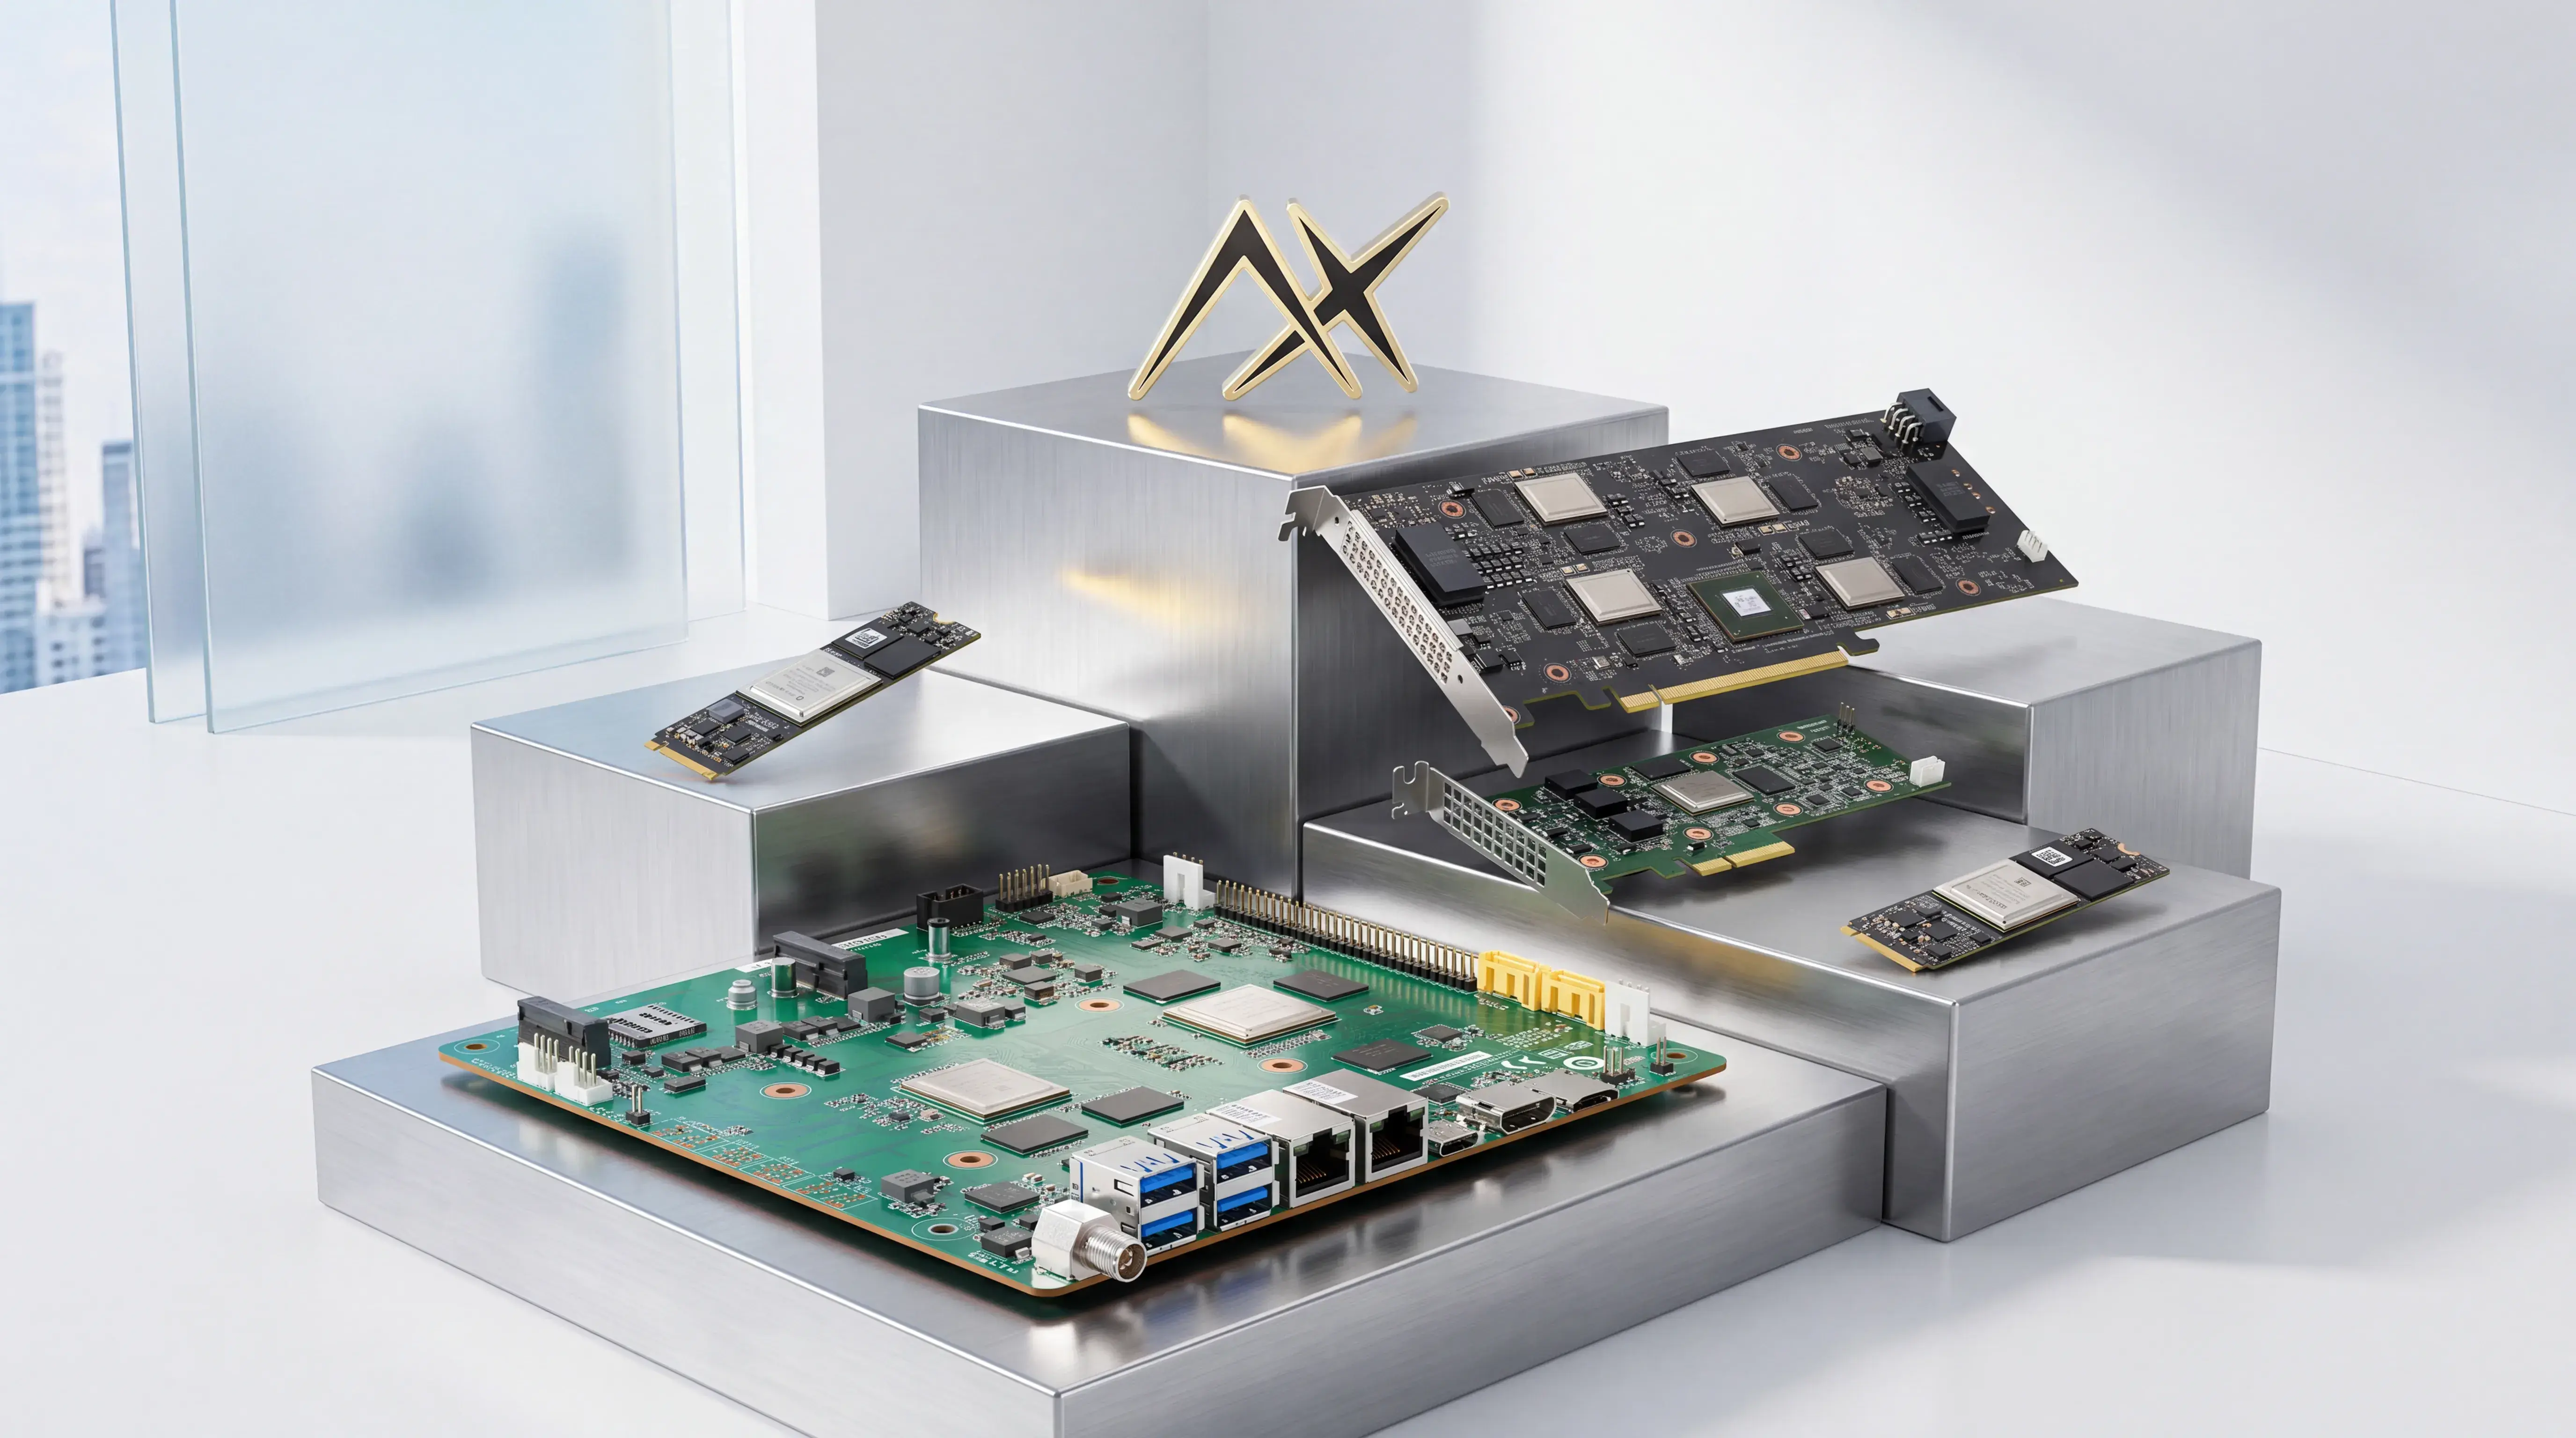
Crafted in Europe, Trusted Worldwide.
Purpose-built AI accelerators that keep your data, your compute, and your analytics under your control. High performance. Low power. No compromise on sovereignty.
Digital in‑memory computing.
Compute inside SRAM. The data stops travelling, the watts stop burning.
-
UP TO
5x
performance per dollar
Cost efficiency with no performance compromise
-
15
TOPS per watt
Demanding workloads without the power, the cost or the heat.
-
99.9%
relative accuracy
Post-training quantization preserves FP32-equivalent accuracy with no retraining
Three ways to deploy.
-
-
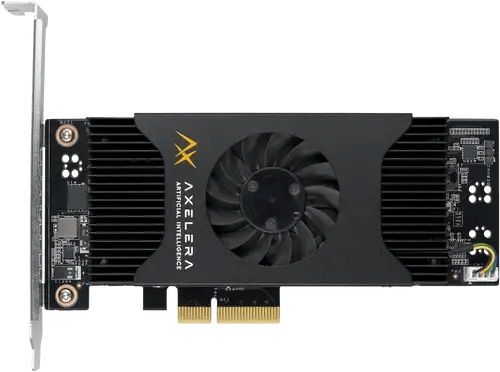
-
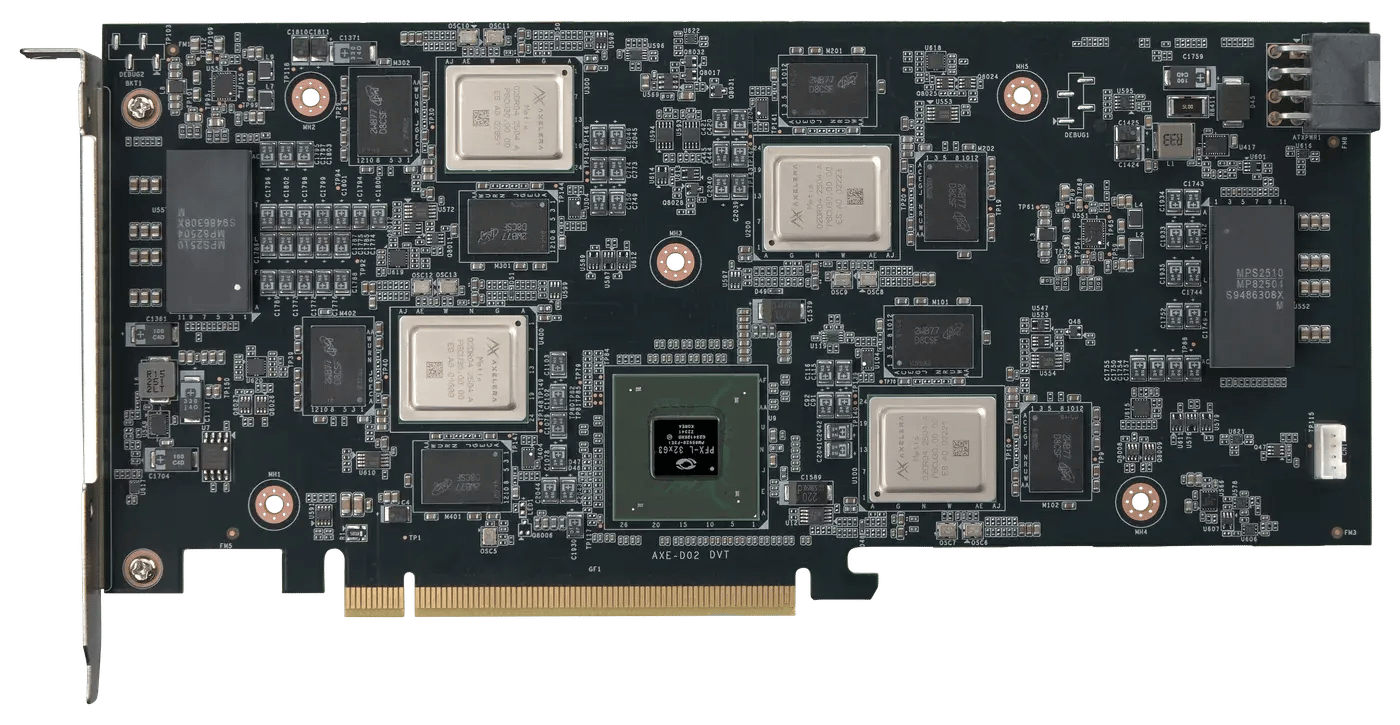
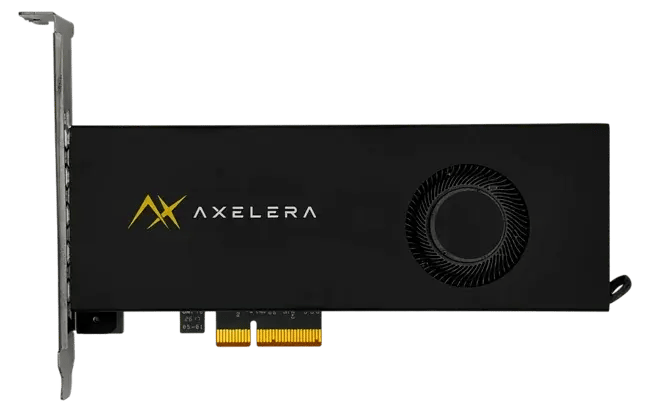
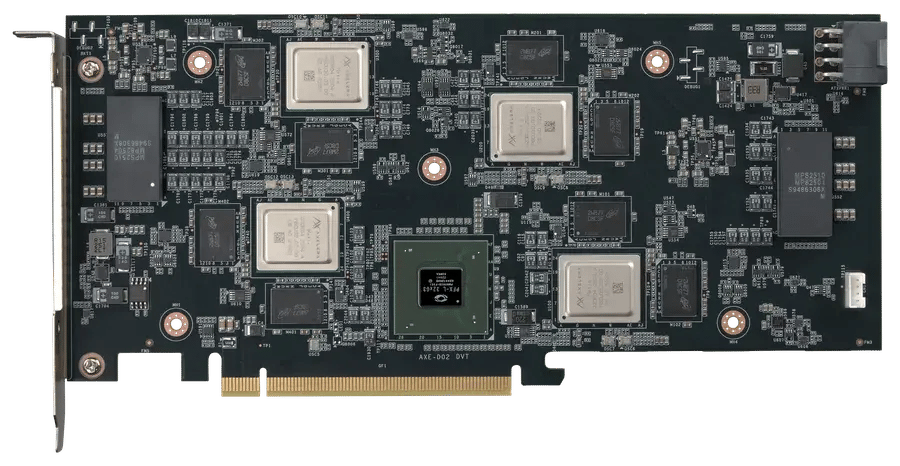
Server
AI at data center scale: multi-AIPU cards that bring inference density to racks and supercomputers.
Ahead on every benchmark.
-
Detection
YOLOv8l, 640 × 640, frames per second
Axelera Metis
0 FPSCompetitor
0 FPS0x -
Throughput
Ultralytics YOLOv7, 640 × 640, frames per second
Axelera Metis
0 FPSCompetitor
0 FPS0x -
Cost efficiency
YOLOv11l, frames per second per dollar
Axelera Metis
0 FPS per $Competitor
0 FPS per $0x -
Energy efficiency
YOLOv11l, frames per second per watt
Axelera Metis
0 FPS/WCompetitor
0 FPS/W0x
Axelera in action
Real-use cases running on Axelera silicon
-
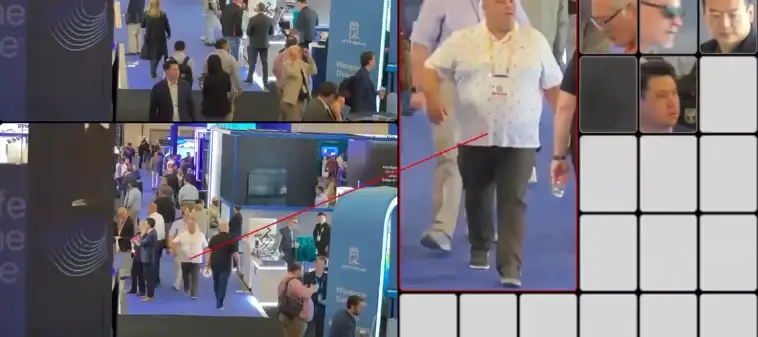
TILED INFERENCE high-resolution scenes sliced into sections, so small objects stay detectable
-
SEGMENTATION AND DETECTION self-checkout: shopper, basket, bags and products masked and labelled, 18.6 to 22.6 fps end to end
-
PPE DETECTION hard-hat compliance across a wall of 24 live streams, with the host CPU at 4%
-
LLM, illustration an on-device language model answering across twelve camera streams
From Chip to Complete System
Choose how you deploy.
-
-
-
-
-
-
Next generation
Three generations, one architecture
One architecture that spans embedded to rack-scale deployments
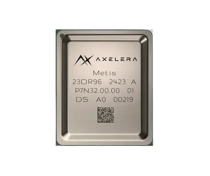
Metis®
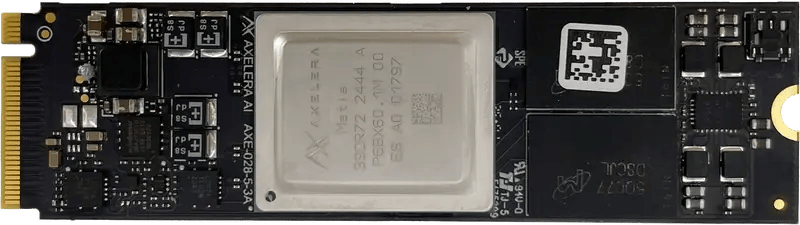
Quad-core AIPU
- Typical application power 3.5-9 W
- Memory up to 16 GB per chip
- LLM capacity up to 8B parameters
- YOLOv8l 181 FPS
- ResNet-50 up to 3,200 FPS
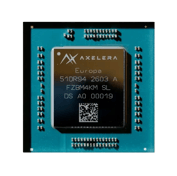
Europa™
Double the cores, sixteen vector units, pre/post-processing on die.
- TDP 45 W per card
- Typical power 30-40 W
- Memory up to 64 GB per chip
- LLM capacity up to 32B parameters
- Qwen3-30B-A3B 53.5 tokens/s
Everything you need to build, faster.
One toolchain, every deployment: describe your pipeline in YAML and the Voyager SDK compiles, quantizes and runs it on any Axelera product line, with no retraining required.
Voyager SDK: the end-to-end software stack
Purpose-built for AI inference: a declarative YAML pipeline language, 100+ supported models through one toolchain, and API compatibility with industry standards. From idea to deployment quickly, with deep customization when you need it.
Describe the workflow in plain language; Voyager Wingman creates and deploys it on device.
The running pipeline, inspected on real Metis silicon without leaving the desk.
Partner Accelerator Network
From hardware to software to distribution, Axelera partners with leading companies to deliver complete AI solutions.
Latest News
Same Amazing Products, Updated Naming
Why WG Tech Deployed 45 Models Instead of One (And Why You Should Too)
How DroneStar AI Scaled One Operator into a Whole Pack
Introducing the New axelera.pro Mini PC
The Future of Security Is Already Running. Here Is What It Looks Like.
What do you need?
-
Not sure which card?
Find the right card with Voyager Wingman.
Describe the workload, the box and the power constraints. Voyager Wingman knows the line-up.
-
Ready to test
Go straight to the shop.
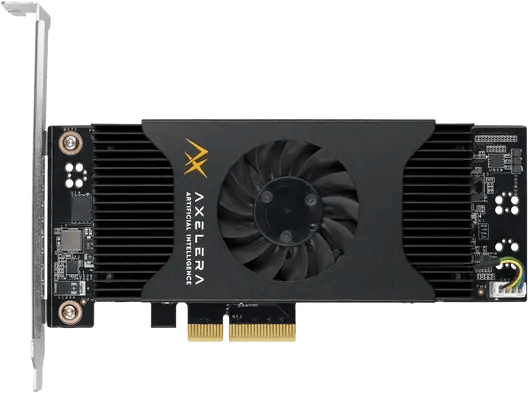
Embedded M.2 modules, compute boards, and Edge and Server PCIe cards, ready to order today.
-
Talk to us