

Your Private, Knowledge-base
Your organization's most valuable knowledge lives in places a public chatbot should never see: engineering wikis, notion notes, confluence pages, incident reports, contract archives, twenty years of email. A retrieval-augmented assistant running on an Axelera Server product puts all of it behind a single prompt box, serving hundreds of employees concurrently, with the index, the embeddings and the model weights all sitting inside your firewall. No third-party processor agreement. No exfiltration risk. No monthly bill that scales with how useful it becomes.
Call Center Automation
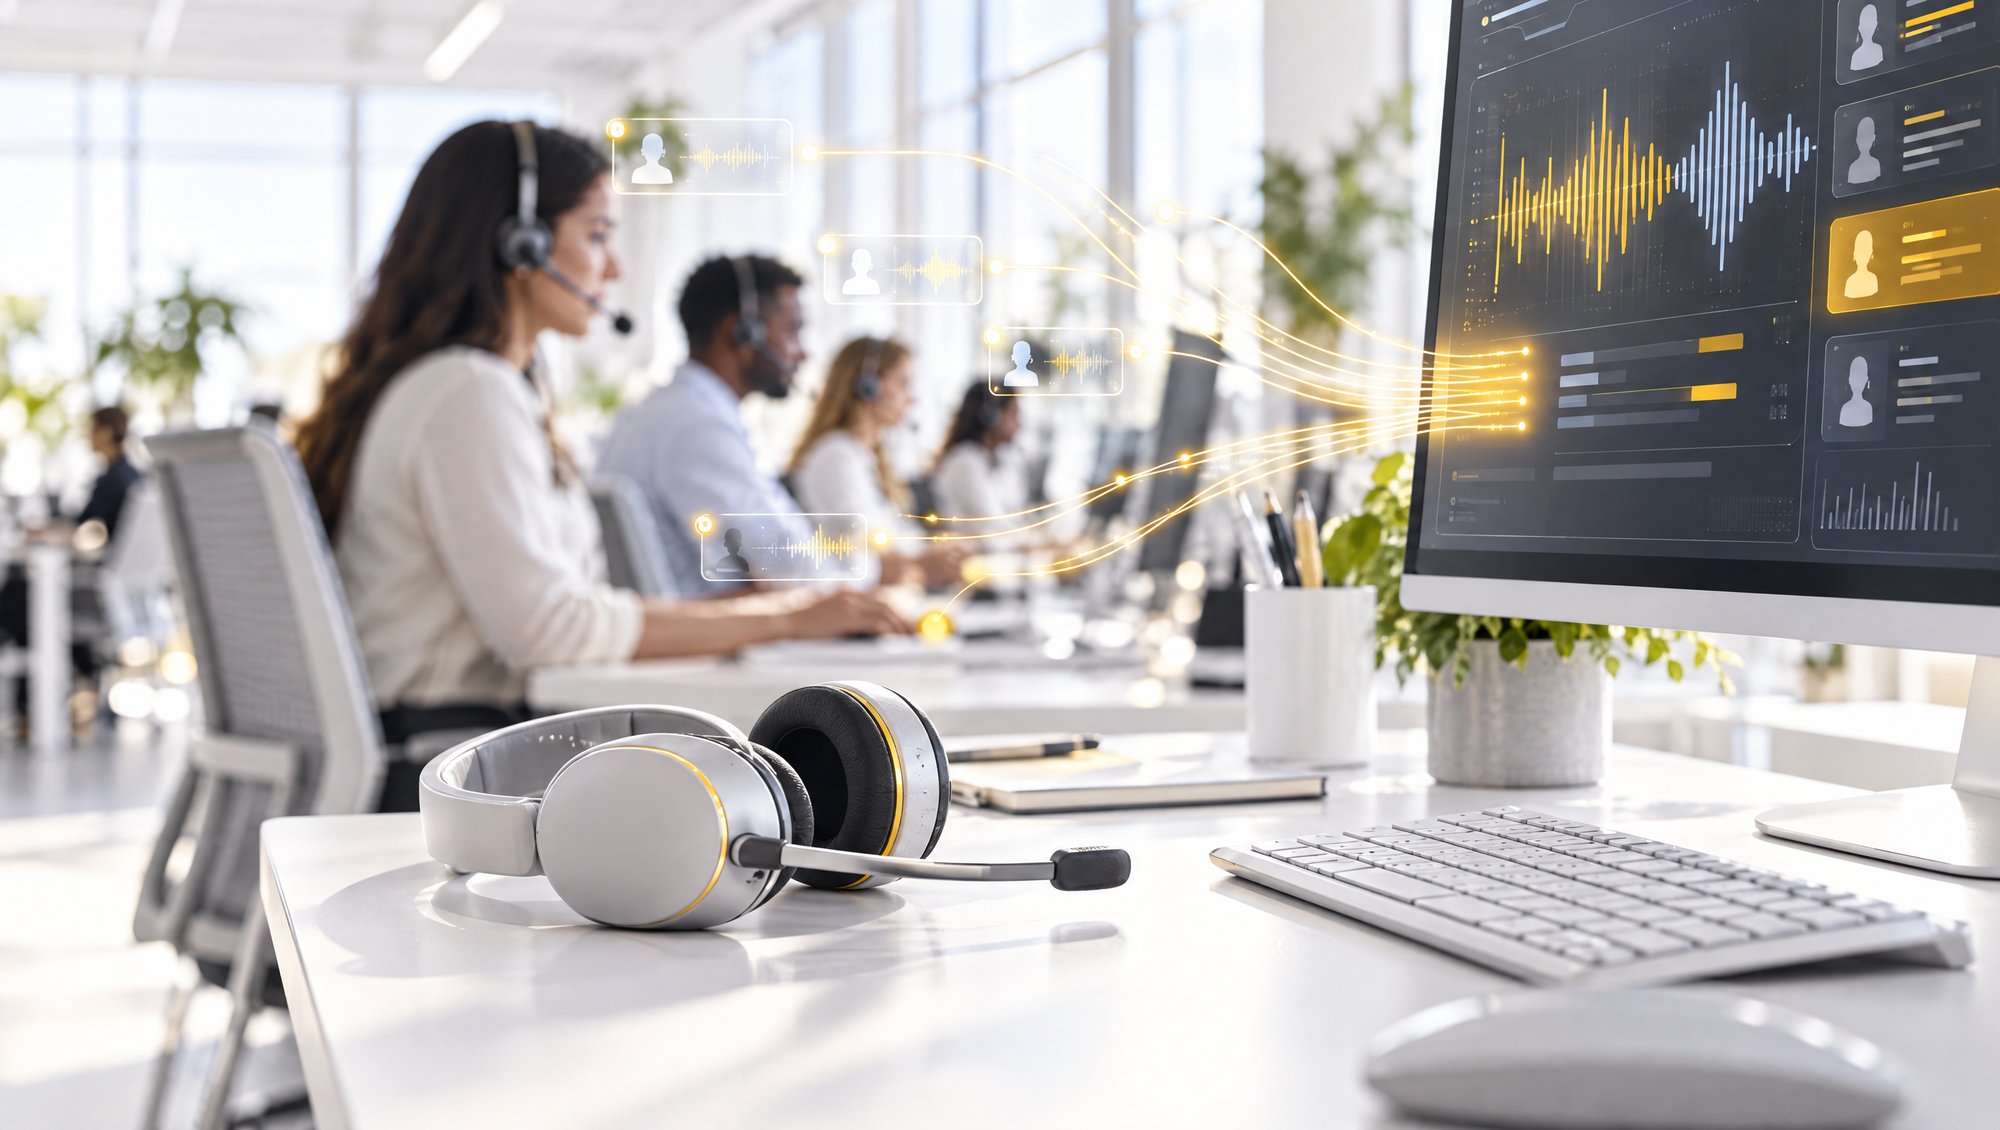
Live call transcription, sentiment tracking, next-best-action prompts and automatic call summaries, all generated before hanging up. Running the speech and language stack on-premise removes the latency of a cloud round-trip and keeps recorded voice, payment details and health disclosures inside the regulatory perimeter where they belong. A single Europa server handles the concurrency of an entire floor at the power draw of a desk lamp.
High Volume Document Processing
Ten thousand claims a day. Fifty thousand clinical notes a month. A contract archive nobody has read since 2011. These are the workloads where cloud inference pricing turns a good business case into a bad one, and where the data is exactly the kind that cannot be sent to a third party.
Batch language model processing on Axelera hardware turns a per-token operating expense into a fixed capital cost, and removes a compliance blocker.
Video Search and Summarization
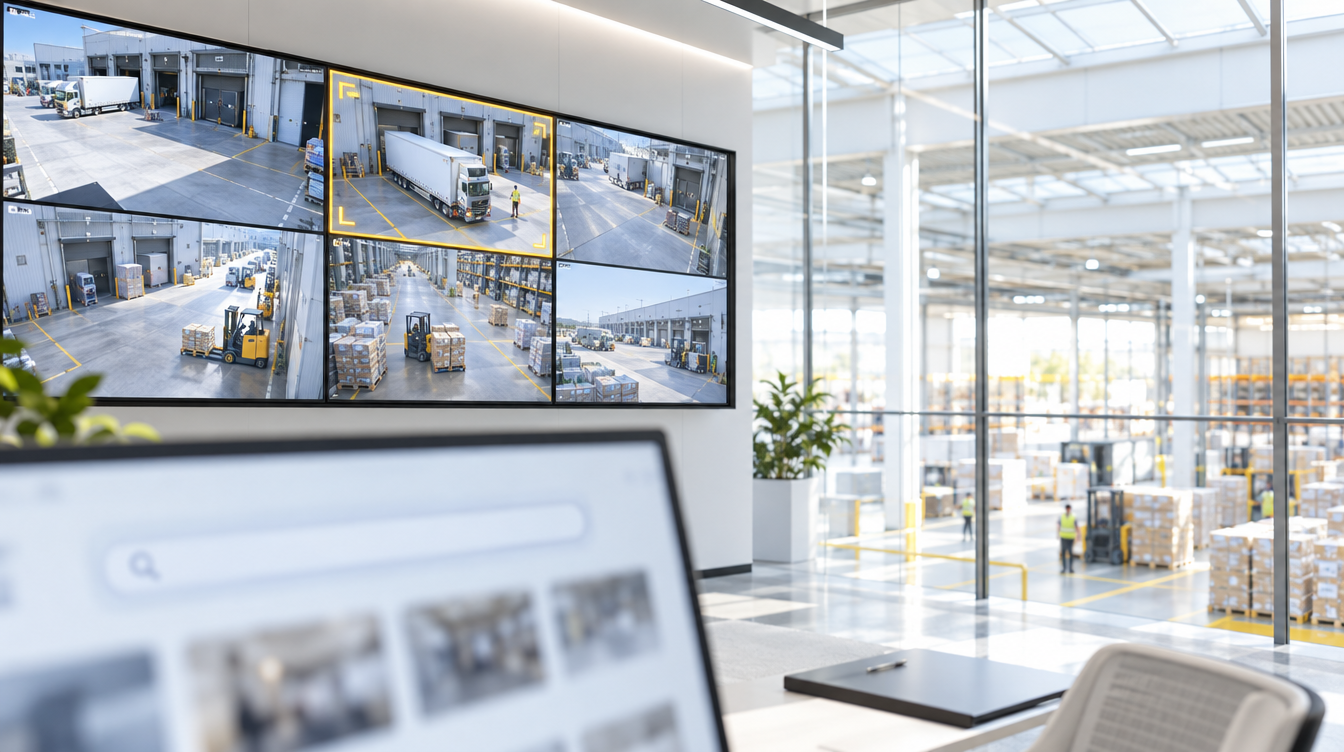
You have thousands, or tens of thousands of hours of video: security footage, product inspection, entertainment content. Searching through that used to take hours. Now, type what you're looking for in plain, natural language and a vision-language model running on Axelera searches hours of recorded footage in minutes. Missing child at an amusement park? Red van at the loading bay after work-hours? A pallet stacked wrong? Find anything with no pre-labelling, no fixed object classes and no clip ever leaving the site. The entire process run on your hardware, within your control; no cloud storage or data movement across boundaries.
Freedom to innovate
The highly cost-efficient, easy-to-integrate and future-proof Axelera® AI Metis® Platform accelerates equipment and software deployment by providing a comprehensive hardware and software solution for accelerating Vision AI in Security and Surveillance. While the hardware design enhances performance and reduces cost and power consumption, the usability of Metis makes vision AI technology accessible to a broader range of developers and enterprises worldwide, so they have the freedom to innovate.
Fabrizio Del Maffeo, CEO & Co-founder explains how axelera.pro addresses market gaps with innovative computer vision AI and AI accelerator hardware, delivering high performance and efficiency for the embedded and Edge spaces at lower power consumption and cost.